
 اخبار
هوش مصنوعی و ارزیابی نوآوری علمی: گزارش جدید AI2 در بستر علمی کاوش
پژوهشی بهروز در AI2 که بررسی میکند LLMها در ارزیابی نوآوریهای علمی به چه اندازه قابل اعتماد هستند و بنچمارک جدیدی ارائه میدهد.
 سیاست و قانون
Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says
AI labs have staked their reputations on model benchmarking — the supposedly neutral and accurate system of evaluations that are designed to measure whether o
 اخبار
The final Disrupt Stage lineup: Three days of conversations you won’t hear anywhere outside of TechCrunch Disrupt 2026
The full TechCrunch Disrupt Stage lineup revealed, featuring Max Hodak, Mark Wahlberg, Benchmark partners, and more. Register now to save up to $100 on your p
 اخبار
The final Disrupt Stage lineup: Three days of conversations you won’t hear anywhere outside of TechCrunch Disrupt 2026
The full TechCrunch Disrupt Stage lineup revealed, featuring Max Hodak, Mark Wahlberg, Benchmark partners, and more. Register now to save up to $100 on your p
 اخبار
Introducing MentalHealthBench
MentalHealthBench is an expert-informed benchmark for evaluating helpful and safe AI responses across realistic mental health conversations.
 پژوهش
How UK AISI and EvalEval Are Making Benchmark Results Reproducible
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
 کسبوکار
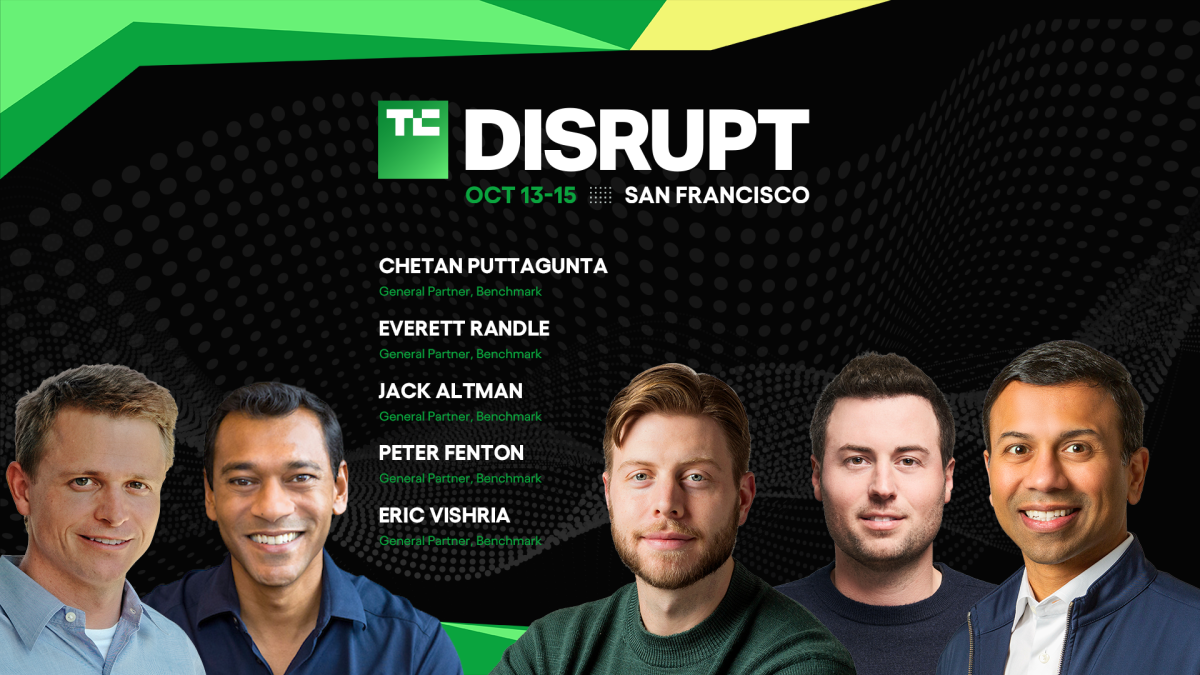
Where will the next breakout startup come from? Benchmark’s full partnership weighs in at TechCrunch Disrupt 2026
Where will the next breakout startup come from? Benchmark’s full partnership weighs in on the main stage at TechCrunch Disrupt 2026. Save up to $200 before Se
 اخبار
Vals, backed by Andreessen Horowitz, is looking to become the gold standard for AI benchmarking
Vals AI is hoping to make AI benchmarking a more neutral and trustworthy resource in a world increasingly inundated by AI models.
 مدلها
Separating signal from noise in coding evaluations
A new analysis from OpenAI reveals issues in SWE-Bench Pro, a popular coding benchmark, raising concerns about reliability and accuracy in evaluating AI model
 پژوهش
ScarfBench: Benchmarking AI Agents for Enterprise Java Framework Migration
A Blog post by IBM Research on Hugging Face