خلاصه خبر
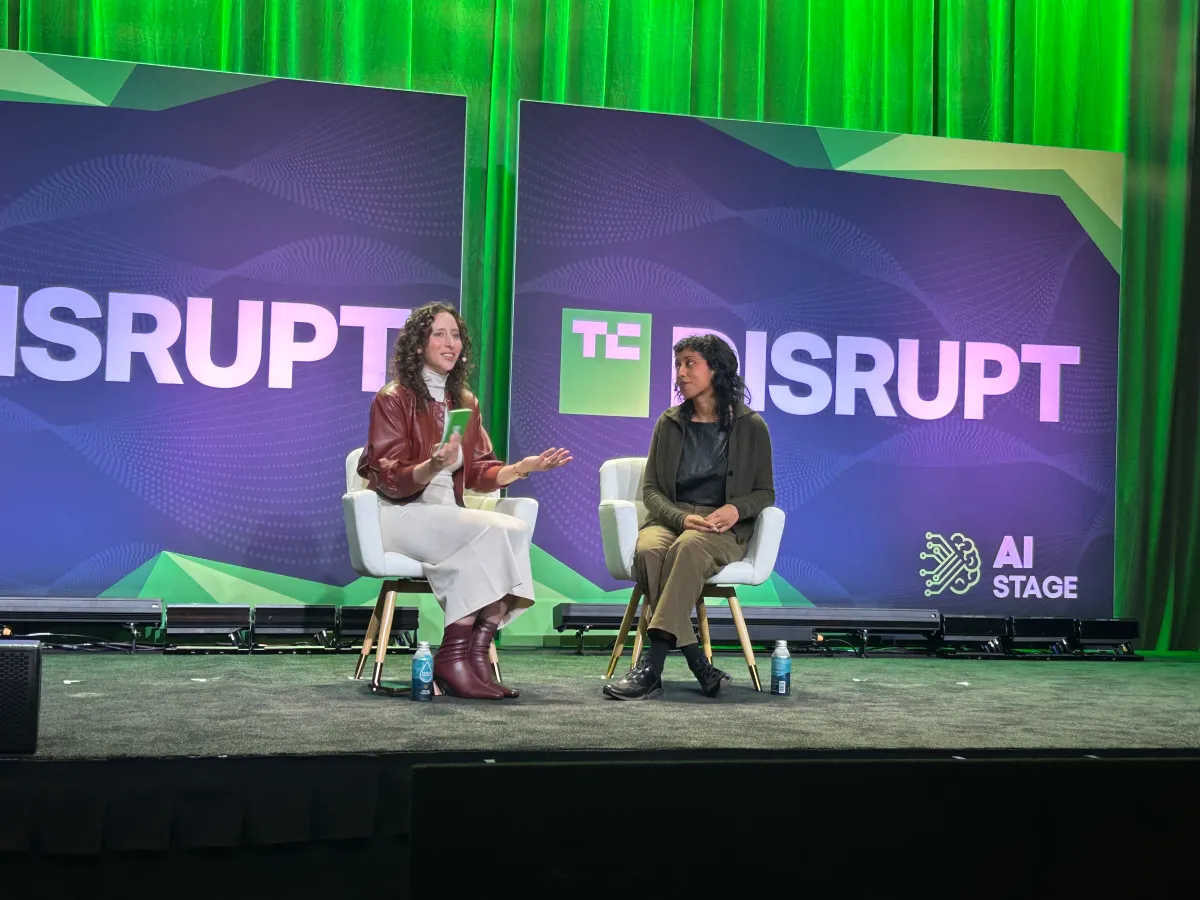
AI labs have staked their reputations on model benchmarking — the supposedly neutral and accurate system of evaluations that are designed to measure whether one AI product is better than another. However, the methods behind these evaluations are complicated and still maturing, said Irene Solaiman, Hugging Face’s chief policy officer, during a discussion at TechCrunch […]
زمینه و جزئیات
Disrupt doors open Oct. 13. Get your pass and bring someone with you at 50% off. REGISTER NOW. Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says Lucas Ropek 3:49 PM PDT · October 19, 2026 AI labs have staked their reputations on model benchmarking — the supposedly neutral and accurate system of evaluations that are designed to measure whether one AI product is better than another. However, the methods behind these evaluations are complicated and still maturing, said Irene Solaiman, Hugging Face’s chief policy officer, during a discussion at TechCrunch Disrupt last week. Testing needs to come together into a more consistent science if the industry is to rely o
چرا برای مخاطب فارسی مهم است؟
کاربران، کسبوکارها و پژوهشگران ایرانی هر روز بیشتر با مدلهای زبانی، تولید تصویر و اتوماسیون هوشمند سروکار دارند. دنبال کردن این خبر کمک میکند تصمیمهای دقیقتری برای کار، آموزش و سرمایهگذاری گرفته شود.
- اثر مستقیم روی ابزارهای روزمره مثل چتبات و جستجو
- تغییر رقابت میان شرکتهای بزرگ فناوری
- اهمیت شفافیت، ایمنی و قوانین هوش مصنوعی
نگاه هما
تحریریه هما این خبر را برای مخاطب فارسی بازنویسی کرده است تا بهجای ترجمهٔ خام، تصویر روشنی از «Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says» ارائه شود. جزئیات تکمیلی را در منبع اصلی بخوانید و اگر میخواهید همین موضوع را عمیقتر بررسی کنید، در چت هما بپرسید.
پرسشهای پرتکرار
موضوع این خبر چیست؟
AI labs have staked their reputations on model benchmarking — the supposedly neutral and accurate system of evaluations that are designed to measure whether o
منبع خبر کجاست؟
این گزارش بر اساس پوشش TechCrunch AI تهیه شده است.