
 اخبار
بهروزرسانی Model Spec اوپنایآی؛ پنج ارزش بنیادین برای همسوسازی هوش مصنوعی
اوپنایآی سند Model Spec را با معرفی پنج ارزش بنیادین بهروزرسانی کرد تا هوش مصنوعی را شفافتر و همسوتر با نیازهای انسانی توسعه دهد. این تغییر گامی مهم برای آیندهای ایمنتر است.
 پژوهش
OpenAI Spec تازه: پنج اصل برای هوش مصنوعی بهتر و مسئولانه
OpenAI با Spec جدید خود، پنج اصل اساسی برای طراحی هوش مصنوعی قابل اعتماد و منصفانه ارائه میدهد؛ از صداقت تا دامنه تصمیمگیری انسانی.
 سختافزار
Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Models
NVIDIA today released Nemotron 3.5 Super VL, an open 120-billion-parameter model that delivers the fastest task completion and highest accuracy for specialize
 مدلها
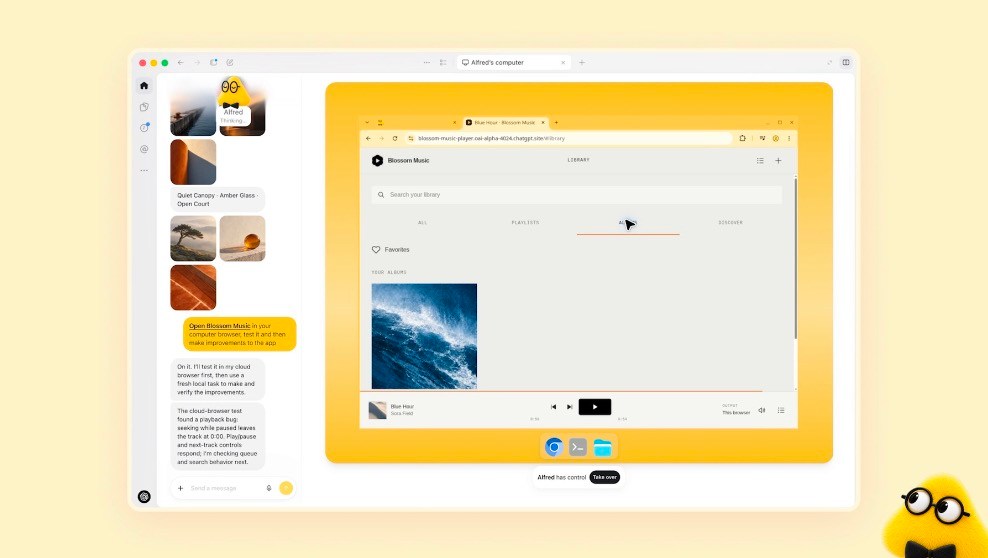
OpenAI launches Dots, its bubbly agentic avatar
Dots are meant to operate independent of any specific hardware or interface, pursuing user-defined goals continuously in the background with minimal oversight
 محصولات
Humans, not rogue AI, are still the biggest cybersecurity risk to energy systems
Before recent high-profile hacks raised the specter of AI possibly "killing all humans," our energy systems were already disturbingly vulnerable to cyberattac
 اخبار
Why Specialization Is Inevitable
A Blog post by Dharma-AI on Hugging Face
 پژوهش
هوش مصنوعی در تولید متن سریعتر: Self‑Speculative Decoding
بهبود سریعسازی تولید متن با استفاده از Self‑Speculative Decoding، که ترکیبی از تحلیل زودهنگام و بازنگری در لایههای LLM است، میتواند سرعت و مصرف حافظه را به طور چشمگیری کاهش دهد.
 پژوهش
هوش مصنوعی به سرعت میرود: Dynamic Speculation در Hugging Face
این خبر، فناوری Dynamic Speculation را معرفی میکند؛ روشی اجمالی و سریع برای تولید متن با سرعت تا ۲.۷ برابر، از Intel و Hugging Face. سریع و دقیق.
 اخبار
حملات هوش مصنوعی: SweetSpecter و تهدیدات سایبری فراگیر-شکاف امنیتی
OpenAI حسابهای متصل به تهدیدات SweetSpecter را مسدود کرد؛ این گروه، وابسته به چین، با هوش مصنوعی آسیبپذیریهای سیستمها را شناسایی و حملات فیشینگ را پشتیبانی میکرد.
 کسبوکار
چگونه مدل هوش مصنوعی با نمایندگیگرا، رشد فروش را 10 برابر میکند
با استفاده از مدل هوش مصنوعی «Agentic Prospecting»، شرکتها میتوانند روند پیشفهرستسازی فروش را هزاربار بهبود بخشند و رشد 10 برابر را تجربه کنند.